An RF SoC wired straight into a GPU by iWave’s own RoCEv2 IP
July 16, 2026
Article
RoCEv2 IP enables ultra-low latency, high-bandwidth data transfer between Direct RF Software Defined Radio (SDR) platforms and GPUs by bypassing traditional host memory bottlenecks. Modern Direct RF SDR systems generate massive volumes of wideband IQ data that must be transferred and processed in real time. Conventional architectures route this data through host memory and CPU software before reaching the GPU, introducing unnecessary latency and limiting overall system performance.
iWave’s RoCEv2 FPGA IP Core overcomes these limitations by enabling zero copy RDMA streaming directly from a Direct RF RF SoC to GPU memory over 100GbE, scalable up to 400GbE. By eliminating the CPU and host DRAM from the sample data path, the solution enables a GPU native SDR architecture capable of real time RF signal processing, visualization, and AI-driven analytics.
Designed as a vendor agnostic solution, iWave’s RoCEv2 IP can integrate with any Direct RF RF SoC and any RDMA capable GPU, providing a scalable framework for next generation radar, electronic warfare (EW), SIGINT, spectrum monitoring, and AI enabled RF applications.
End-to-End RF SoC to GPU Data Flow
- Any Direct RF RF SoC featuring multi channel ADCs/DACs with sampling rates up to 64 GSPS and wideband RF support up to 32 GHz performs Digital Down Conversion (DDC), decimation, and channelization within the FPGA fabric, generating packed IQ data streams for high throughput transport.
- The iWave RoCEv2 FPGA IP functions as an integrated RDMA initiator, issuing RDMA WRITE operations directly from the RF SoC over 100 GbE (QSFP28) which can be expanded up to 400G, eliminating the need for host CPU involvement in the data transfer path.
- A 100G RDMA capable NIC together with NVIDIA GPUDirect RDMA (peer memory kernel module) enables peer to peer PCIe Gen4 x16 transfers, placing IQ samples directly into GPU VRAM while completely bypassing host DRAM.
- Once the IQ data resides in GPU memory, CUDA based processing pipelines including cuFFT, polyphase channelization, demodulation, and RF parameter extraction using NVIDIA Holoscan, Rivermax, or equivalent frameworks deliver real time visualization of time domain, spectrum, constellation, and waterfall displays directly from GPU memory.
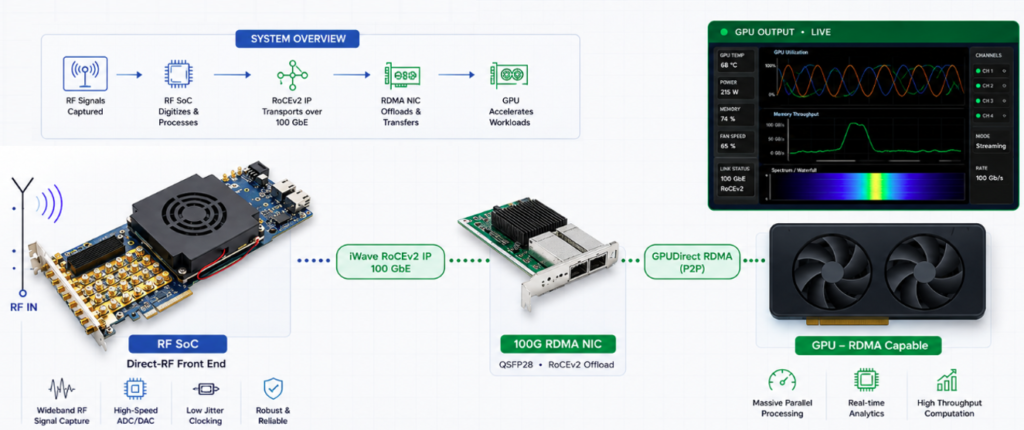
The IP that removes the host bottleneck: iWave RoCEv2 IP Core
Because the RoCEv2 initiator is implemented as iWave’s FPGA IP, the RF SoC can issue RDMA WRITE operations directly into a registered ring buffer in GPU VRAM, eliminating intermediate software copies and minimizing CPU intervention. The 100G RDMA NIC and GPU operate within a shared PCIe peer to peer (P2P) domain, allowing data to flow directly between the FPGA and GPU while the CPU is responsible only for initialization tasks such as queue-pair creation, memory registration, and connection management.
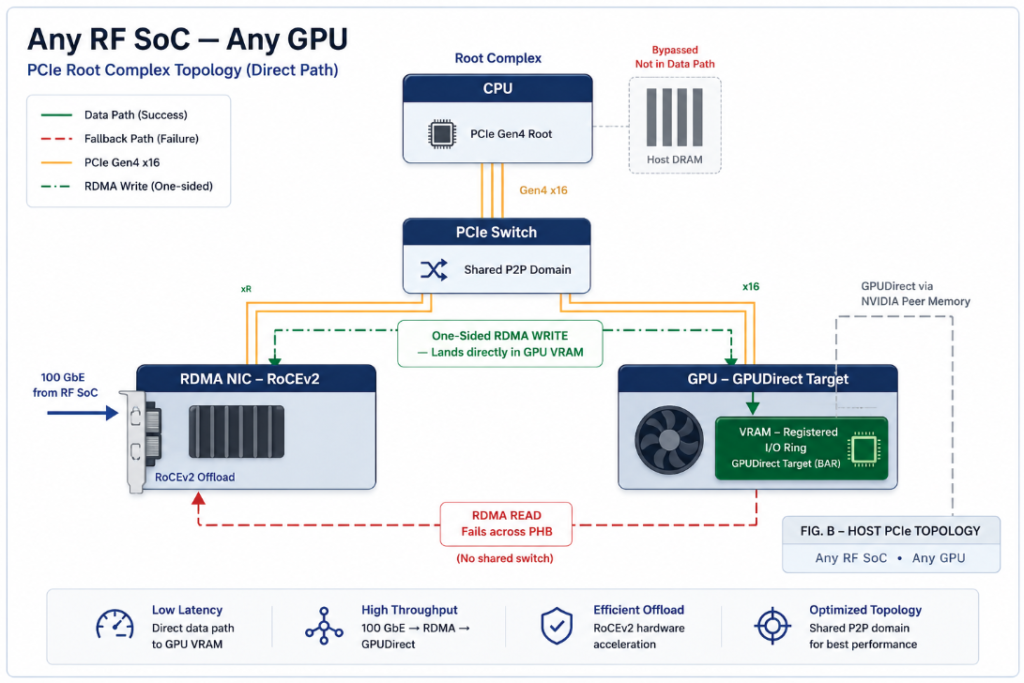
This architecture completely bypasses host DRAM, enabling a zero copy, ultra-low-latency data path from RF acquisition to GPU memory. By eliminating unnecessary memory transfers and CPU overhead, the solution sustains deterministic high throughput streaming for demanding real time applications such as wideband spectrum monitoring, electronic warfare (EW), SIGINT, radar signal processing, and AI/ML inference. The result is a GPU native RF instrument, where RF samples are captured, transported, processed, and visualized entirely within the FPGA to GPU data path, maximizing system efficiency and enabling scalable multi channel, high bandwidth signal processing.
Benefits of a GPU Native SDR Framework
- Zero copy Datapath : Sample data never enters host DRAM, the iWave RoCEv2 IP delivers it to VRAM, so the CPU is off the critical path entirely to achieve ultra low latency and zero copy data movement.
- WRITE driven by design : Matches PCIe P2P reality; liveness is tracked via NIC hardware counters and in band IQ sequence numbers.
- Software defined receiver : Retune centre frequency, resize the FFT, or add a channel in GPU software no bitstream re spin. The radio is code.
- Scales up : The same IP + GPU Direct path extends to multi GPU channel fan out and inline Tensor RT signal classification spectrum intelligence, not just display.
|
64 GSPS DIRECT-RF |
10-14 bit ADC / DAC |
to 32 GHz RF REACH |
100-400 GbE iWave, RoCEv2 |
Gen4/5 x16 P2P → VRAM |
GPUDirect → GPU VRAM |
The Takeaway
As RF systems continue to demand higher bandwidth and lower latency, traditional CPU centric data paths become a major limitation. iWave’s RoCEv2 FPGA IP removes these bottlenecks by enabling direct RDMA streaming from Direct RF RF SoCs to GPU memory over high-speed Ethernet.
By combining zero copy data movement, GPU acceleration, and vendor agnostic integration, the solution provides a scalable foundation for GPU native SDR platforms capable of real-time spectrum analysis, radar processing, electronic warfare, and AI-driven RF applications.
Whether developing next generation defense, aerospace, telecommunications, or high performance embedded systems, iWave’s RoCEv2 FPGA IP enables developers to build flexible, high-throughput architectures that maximize GPU performance while minimizing system latency.